New LongCat
Meituan Totoro Native Multimodal Large Model
Introduction
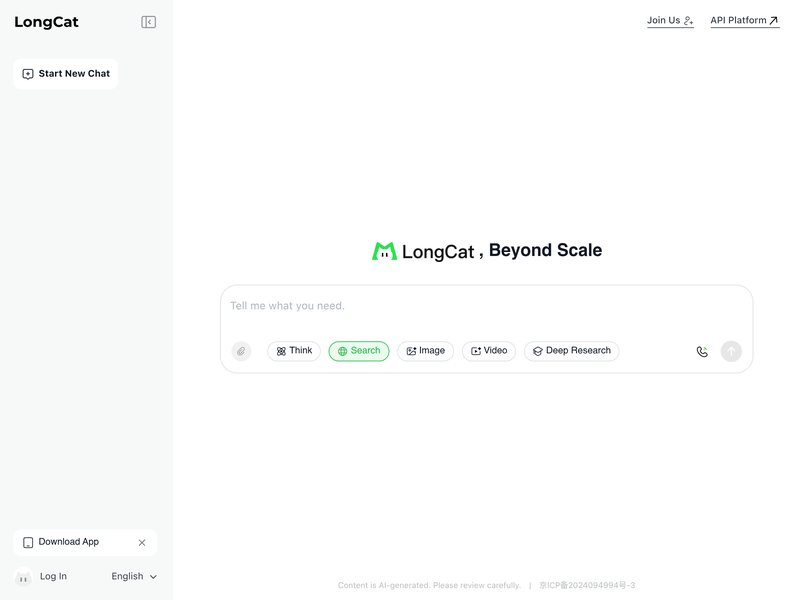
LongCat is a large-scale model developed by Meituan’s Dragon Cat team. Its web version can be accessed via longcat.chat, and API access is also available. The LongCat-2.5 version, released on November 1st, features a total of 1.6 trillion parameters; each token activates approximately 48 billion computational resources when used. This model is particularly designed for tasks that require long-duration operations by intelligent agents.
Compared to the previous generation, it now boasts native image-processing capabilities: images are encoded into discrete tokens, which are processed along the same main pipeline as text data. In the official demonstrations, tasks such as fluid simulations and 3D scene rendering, which require both coding and visual analysis, were demonstrated. A total of 1 million tokens are used to represent the relevant context in this process.
Version 2.0 is open-source, while the availability of GitHub and HuggingFace interfaces for version 2.5 is currently indicated as “coming soon”. All official performance tests are conducted internally; there is very little third-party data available at present. If you plan to use it in a production environment, it is safer to test it with your own tasks for at least a week first.
Related reading: "LongCat-2.5, GLM-5.3, DeepSeek V4.1 Flash: Meituan’s report card featuring 31 rows of results—every row in its own column consists solely of self-test scores."
Related