New Liquid AI
Lightweight base models running at the edge
Introduction
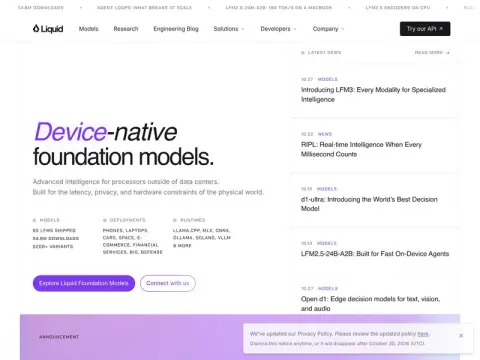
Liquid AI is a company that emerged from MIT laboratories. Its approach differs significantly from that of the mainstream large-scale model companies: instead of focusing on increasing the number of parameters, it specializes in developing small models that can run locally on smartphones, laptops, cars, and robots. These models are part of its LFM series.
Its model features low latency and minimal resource consumption. Examples provided by the developers include a MoE model with a total of 24 billion parameters—in which only 2 billion parameters are activated at a time—running at a rate of 184 tokens per second on a MacBook; moreover, models with a size of less than 1GB are sufficient to drive local agents. The new generation of LFM3 releases six models at the 2B parameter scale simultaneously, covering scenarios such as text processing, visual analysis, and device-side agent applications—without the need for data to leave the device itself.
Models can be deployed using common frameworks such as llama.cpp, MLX, ONNX, and CoreML. The total number of downloads has exceeded 50 million times, and Mercedes-Benz has also used these models for in-vehicle private AI applications. These models are ideal for developers who need to create client-side applications with high requirements for privacy and response speed. Some of the model weights are available publicly; however, commercial use may require specific licenses.