Create a video instantly.
An AI short-video tool that creates the audio first and then matches it with visuals.
Introduction
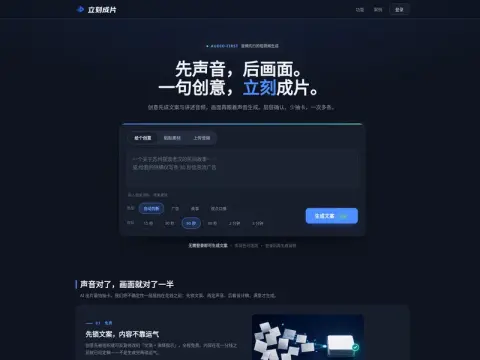
LickV takes the opposite approach to most AI video tools: while others generate the visuals first and then add voiceover, it starts with the audio and then creates the visuals.
What you input can be a single idea, a draft, or even an audio clip. The AI then handles copy organization, sound design, timed storyboarding, storyboard design draft confirmation, and automatic video script generation in sequence, before finally assembling a narrated short video with visuals. The line on the official website—“Get the sound right, and the visuals are half right”—pretty much sums up the product philosophy.
This order does make more sense for talking-style content. In formats like educational explainers, opinion monologues, and product walkthroughs, the rhythm is dictated by the voice—when to pause, when to emphasize—and the visuals simply follow. If you lock in the audio first and then lay out the visuals, the sync points are naturally accurate; doing it the other way around means constant fine-tuning.
What it’s not suited for is content that relies primarily on visual impact—for example, purely visual creative short films. In those cases, sound plays a supporting role, and using this workflow actually feels awkward.
Before shooting a vertical short drama, check TVLab to see how hit shows in the same genre open and which episode delivers the twist. Then pick an inspiration card with pre-broken-down storyboards and generate shot by shot.
Related