Doubleword
Batch inference cloud for open-source models
Introduction
Doubleword is an inference cloud built for high-volume workloads, specializing in asynchronous and batch tasks for open-source models. It is not positioned to provide real-time APIs for chat applications; instead, it handles jobs that involve hundreds of thousands of records at a time, can tolerate waiting, and are extremely sensitive to unit cost: data labeling, document batch processing, offline evaluation, and corpus cleaning.
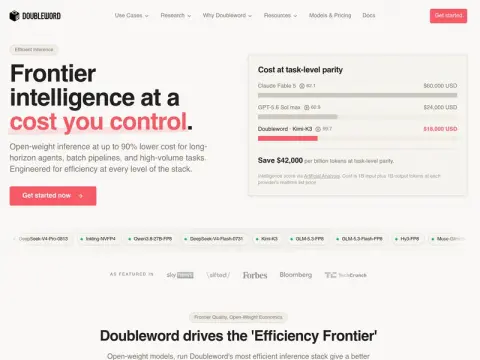
The comparison basis given on the official website is that, at equivalent task quality, it is much cheaper than closed-source frontier models, mainly by relying on open-source weights plus scheduling optimizations for batch scenarios. The logic of this approach is sound—batch tasks can keep GPUs fully utilized, and once utilization goes up, unit costs naturally come down.
Before choosing it, be clear about one thing: whether you can accept the quality of open-source models on your tasks. For some tasks, the gap between open-source and closed-source models is small, and running in batches can save a lot of money; for others, the gap is obvious, and the savings will be eaten up by rework. I recommend running an A/B test on a small sample first before deciding whether to switch.
Related